A contact center vendor evaluation is defensible when a different team, using the same rubric and evidence, would reach the same answer. In 2026, that means locking weights before demos, blending stakeholder input with a documented points method, tying every score to evidence, and stress-testing the winner before anyone signs.
Why it matters: Contact center technology vendor evaluation rarely falls apart over criteria. It falls apart over weights. When stakeholders cannot see how their input shaped the decision, they relitigate it, and your selection timeline slips by a quarter.
We didn’t study contact centers. We ran them. We have been the operators stuck in that meeting, and we have watched a good decision die because nobody could explain the math behind it. If you need the criteria themselves, start with our vendor evaluation rubric. This post covers what comes next: weighting, stakeholder input, and proof.
Key takeaways
- Weights decide the outcome. Most evaluations fail over how criteria are weighted, not over which criteria were chosen.
- Show the math. Blend stakeholder input with a visible points method instead of another meeting.
- Structure beats intentions. Sealed pricing, independent scoring, and locked weights are what make an evaluation unbiased.
- Keep the packet. Weighting record, evidence log, sensitivity results, and a one-page decision memo answer the challenge in advance.
What makes a contact center vendor evaluation defensible?
A scorecard is defensible when it passes three tests. It is repeatable: a different team using the same rubric and evidence would reach the same answer. It is traceable: every score points to evidence, and every weight points to a stakeholder decision made before demos. It is independent: the process has built-in controls against bias, including your own.
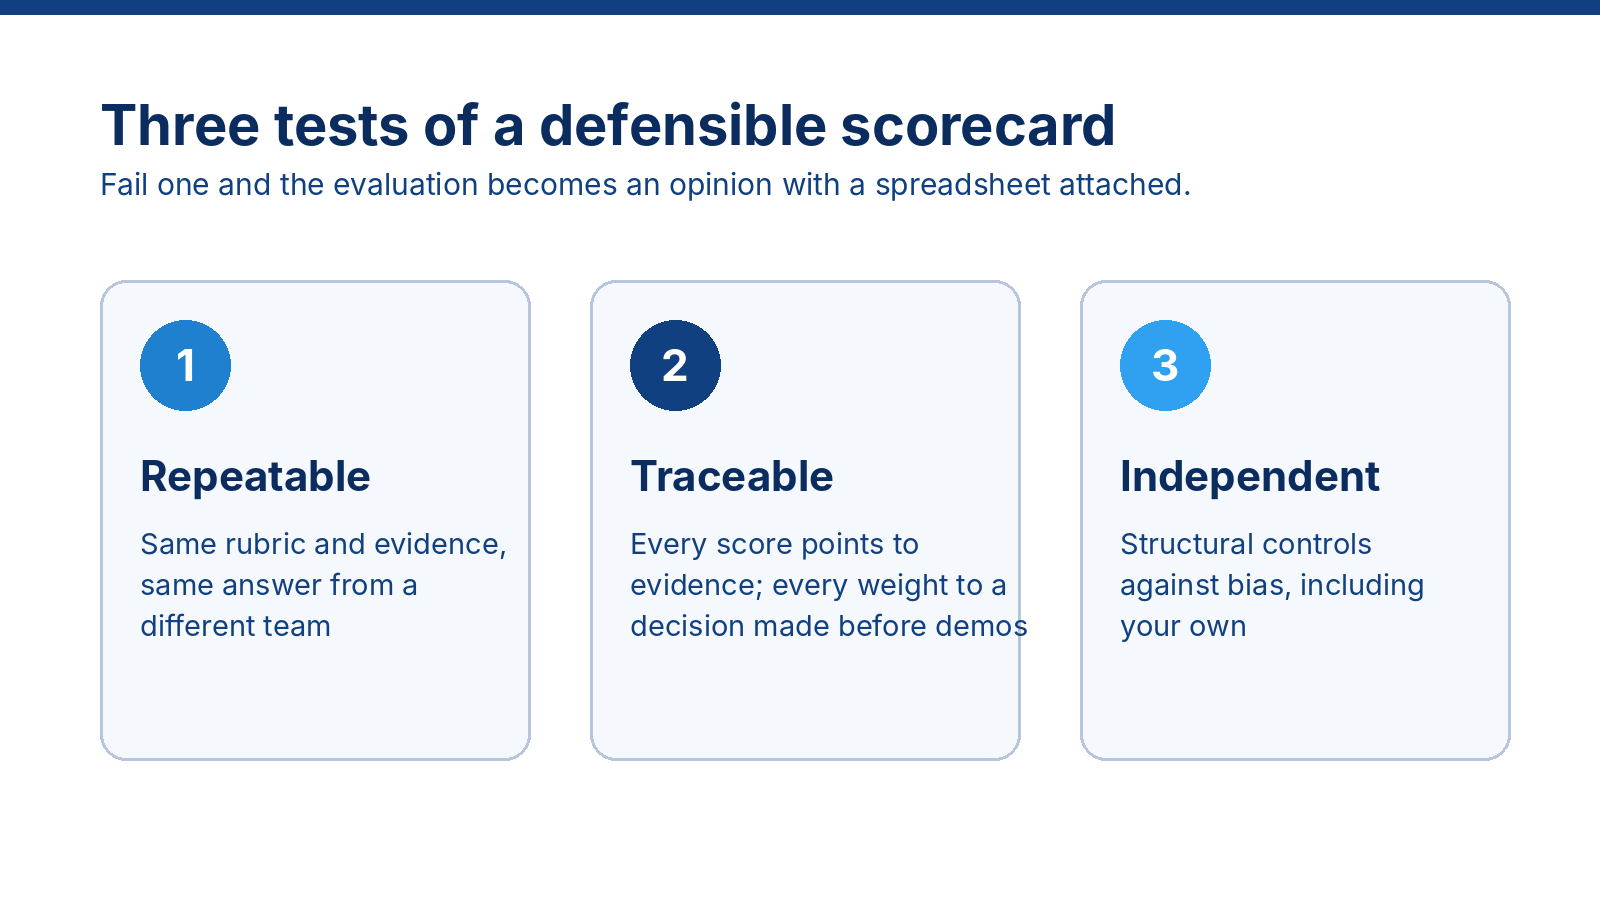
Fail one test and your technology assessment becomes an opinion with a spreadsheet attached. The six steps below are how we keep all three intact.
How should you tier requirements before scoring?
Not every requirement deserves a weight. Sort them into three tiers before anyone scores a vendor.
Knockouts. Pass or fail only: compliance (HIPAA, PCI DSS, SOC 2), must-have integrations, and a budget ceiling. These never get points because they cannot be traded against anything else.
Weighted criteria. The five to eight factors that decide the outcome: operational fit, total cost of ownership, integration depth, implementation risk, agent experience, verified AI, and vendor viability.
Tiebreakers. Nice-to-haves you consult only when finalists land within a few points of each other.
A common failure is 40 weighted line items worth 2.5% each. At that point nothing matters, so the demo wins by default.
How do you blend stakeholder input with math instead of meetings?
This is where most contact center software evaluations lose defensibility. The fix is a simple, visible method with three moves.
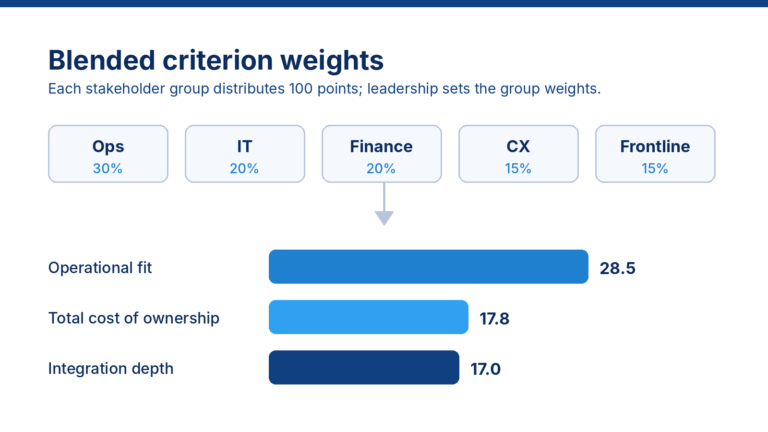
Set group weights first. Leadership decides how much each stakeholder group counts. For example: Operations 30%, IT and Security 20%, Finance and Procurement 20%, CX and Quality 15%, frontline supervisors and agents 15%.
Give each group 100 points. Each group distributes its points across the weighted criteria, independently and in writing.
Calculate blended weights. Multiply each group’s allocation by its group weight, then add the results. Here is an illustrative example for three criteria. The numbers are made up to show the method, not benchmarks.
| Criterion | Ops (30%) | IT (20%) | Finance (20%) | CX (15%) | Frontline (15%) | Blended weight |
|---|---|---|---|---|---|---|
| Operational fit | 40 | 15 | 15 | 30 | 40 | 28.5 |
| Total cost of ownership | 15 | 10 | 45 | 10 | 5 | 17.8 |
| Integration depth | 10 | 45 | 10 | 10 | 10 | 17.0 |
Two things happen. Every stakeholder can see exactly how their input moved the result, and the argument moves out of the demo debrief into a documented decision made before any vendor walks in. Include frontline supervisors and agents. They live in the desktop eight hours a day, and they are the group most likely to be left out.
How do you anchor the scoring scale?
“Rate integration depth from 1 to 5” invites five evaluators to use five different scales. Define what each score means before anyone scores. Here is how that looks for one criterion.
| Score | What it means for integration depth |
|---|---|
| 5 | Native, bidirectional integration with your CRM and WFM, running in production at a comparable customer you have spoken with |
| 3 | Integration exists but is one-directional, middleware-dependent, or unproven at your scale |
| 1 | Custom build, roadmap item, or “our partners handle that” |
Anchor 1, 3, and 5 for every weighted criterion. The in-between scores take care of themselves.
Which bias controls actually work in vendor selection?
An unbiased evaluation does not come from good intentions. It comes from structure.
- Lock weights before demos. Weights changed after a great demo are preferences written down after the fact.
- Score functionality before seeing price. Keep pricing sealed until functional scoring is done. Otherwise the cheapest vendor somehow wins on usability too.
- Score independently first. Evaluators submit scores before any group discussion. Big gaps between scorers are worth discussing, and averages hide them.
- Script every demo. Same scenarios, same order, same time box. Strong vendor demo management keeps the evaluation about your operation, not their highlight reel.
- Disclose relationships. Anyone with a prior tie to a vendor says so, on the record.
How do you stress-test the result before announcing a winner?
Run a sensitivity check. Move each major weight up and down five points and recalculate. If the winner holds, you have a decision. If the winner flips, you have a tie, not a winner, and you should return to tiebreakers, reference calls, or a proof of concept.
It takes about 20 minutes in a spreadsheet, and it is the best answer you will have when someone asks, “What if we had weighted cost higher?”
What belongs in the audit trail?
Your final vendor comparison should fit in one packet: the weighting record with group weights, point allocations, and the date they were locked; an evidence log naming the source behind every score; the sensitivity results; and a one-page decision memo in plain English covering why this vendor, what you traded off, and what risks you are accepting.
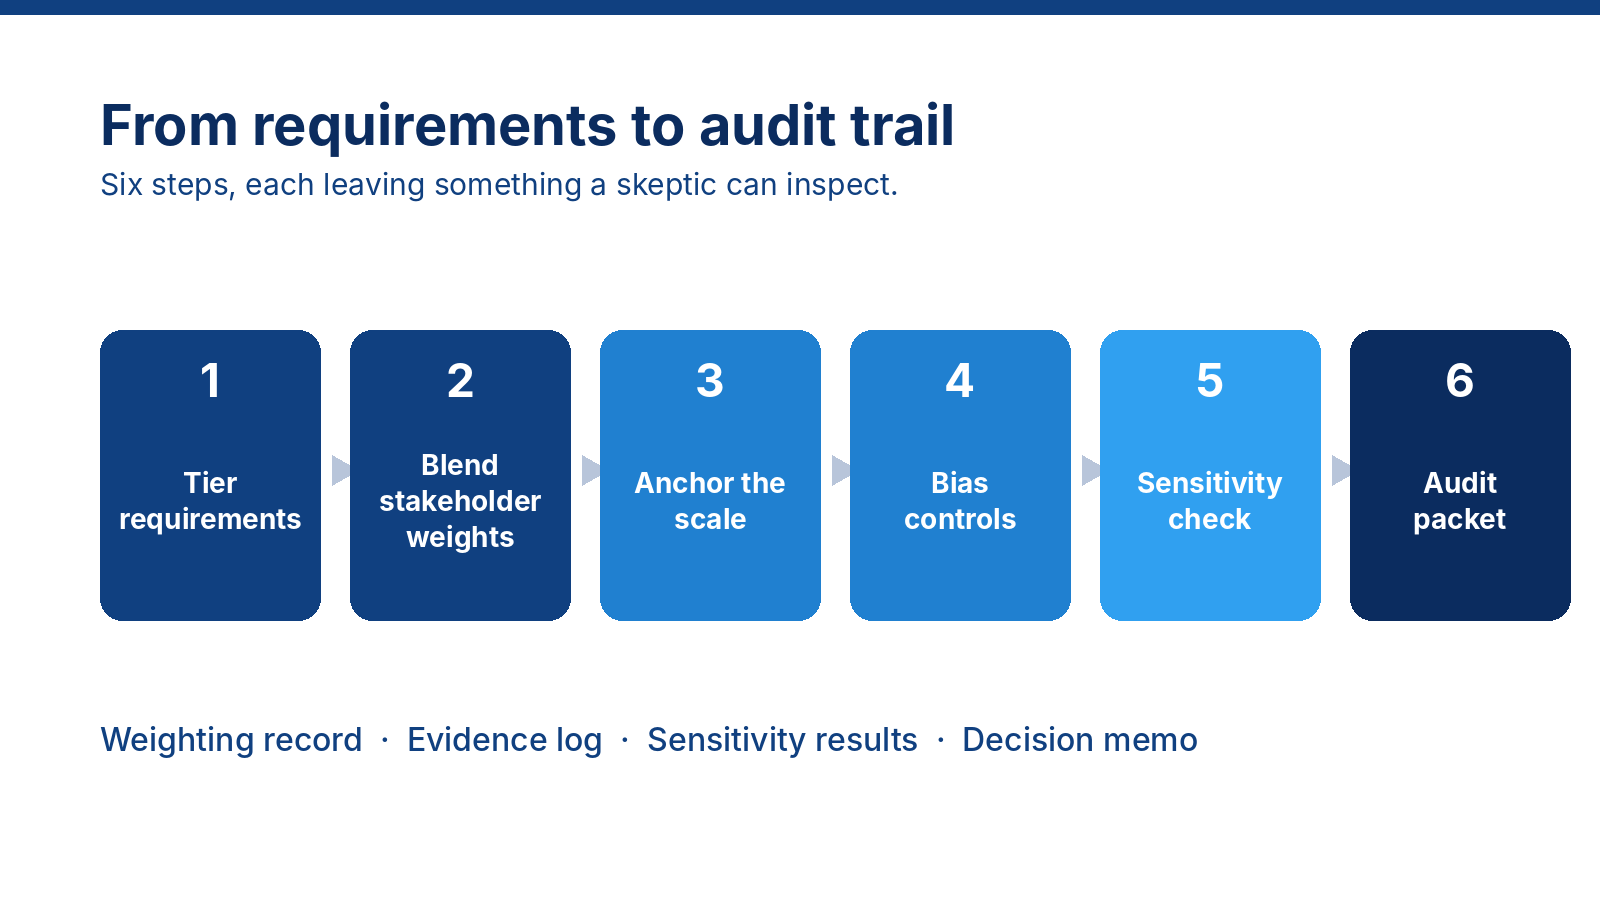
If the decision gets challenged in six months, that packet answers it without anyone rebuilding history from memory.
What are the common failure modes?
The HiPPO override. The highest-paid person’s opinion outranks the rubric. If leadership wants final say, give it a visible weight in the stakeholder step instead of an invisible veto.
Weight creep. Criteria quietly get reweighted mid-evaluation to fit a favorite. Locked, dated weights prevent it.
Evidence-free scores. “Felt intuitive” is not evidence. A task completion time from a scripted demo is.
Frequently asked questions
How do you make a contact center vendor evaluation defensible?
Lock weights before demos, blend stakeholder input with a documented points method, anchor your scoring scale, link every score to evidence, and run a sensitivity check before naming a winner. Then keep the packet. Defensible means someone who was not in the room can follow the reasoning.
How should stakeholder input be weighted in vendor selection?
Leadership assigns each stakeholder group a weight, then each group distributes 100 points across the weighted criteria independently and in writing. Multiply and add to get blended weights. The math shows exactly how each group shaped the outcome, which keeps the argument out of the demo debrief.
What is a sensitivity check in a vendor scorecard?
A sensitivity check moves each major criterion weight up and down, typically five points, and recalculates the ranking. If the top vendor stays on top, the decision is robust. If the leader flips, you have a tie, and you need more evidence from references, tiebreakers, or a proof of concept.
Should price be scored with functionality?
Score price separately. Keep pricing sealed until functional scoring is complete, so cost does not quietly color judgments about usability or fit. Then bring cost in through the total cost of ownership criterion, using one 36-month template from every vendor so the numbers compare like for like.
How many criteria should a vendor scorecard have?
Five to eight weighted criteria is a workable range. Pass/fail items belong in a knockout tier, and nice-to-haves belong in a tiebreaker tier. Forty weighted line items at 2.5% each means nothing matters, so the best demo wins by default and the scorecard becomes decoration.
Where CTG fits
Cloud Tech Gurus is a vendor-neutral CX consultant for enterprise contact centers, built by former contact center executives. We run this process with you across a network of 250+ suppliers and 40+ BPOs, and every weight and score can be audited.
Our standard, stated plainly: we are compensated by suppliers when a client selects one. We disclose that position per vendor, in writing, before any shortlist is built, and scoring criteria are agreed with you before vendors are invited. If a rubric cannot survive being published, it is not a rubric.
Depending on where you are, that can mean no-cost vendor sourcing and a documented shortlist, guru-led sourcing with stakeholder weighting workshops, scripted demos, sealed pricing, and the final decision packet, or CTG Consulting when your team needs to align before it evaluates. You keep ownership of what winning means.